Monday, August 12, 2013

Good resources for science writing/speaking?

For a psychology graduate class I'm teaching this fall (on speaking/writing for general audiences), I'm trying to create a list of good resources on writing, speaking, and blogging about science. I'm hoping that you can help. 

I'm particularly interested in finding good discussions of the value and risks of blogging, suggestions for best practices in writing/speaking, etc. Do you have a favorite go-to source for such advice? Do you know of helpful resources for beginning science writers and speakers? If so, please leave them in the comments (or send them to me directly). I'll compile the full list and will post it here.

Wednesday, August 7, 2013

Stop the presses

Yesterday I encountered something I've never seen before: a formal press release from an academic society (SPSP) about a conference presentation of unpublished research:
http://www.eurekalert.org/pub_releases/2013-08/sfpa-vgb080213.php
A friend of mine forwarded it to me because it makes claims about the cognitive benefits of video game training, an area fraught with methodological problems that my colleagues and I have written about extensively (e.g, here's a recent blog post about a recent critique of such interventions). My guess is that the design shortcomings we discussed in that paper undermine the claims that these authors are making. But, I have no way to know. The actual research isn't available.

 Why does this work merit a press release now, before the research has been published? 

 The purpose of a press release is to draw public (and media) attention to a new finding, but in this case, the press release effectively is the finding because nobody can access the actual research. Journalists or science writers covering this study will have no more information than is available in the release itself, so they cannot verify that the research actually shows what the release claims that it does. In other words, the press release encourages churnalism rather than science reporting.

 In my view, academic societies should not be encouraging media coverage of research until the actual research is available for popular consumption. Doing so risks misleading the public. For this particular release, if the studies suffer from the problems we discussed in our recent article, then the conclusions might be unjustified and there would be a reasonable chance that the research would not survive the peer review process (I can only hope that reviewers would nix publication if the claims aren't justified). If that happened, then the press release would have hyped vapor-findings, claims that lack any underlying support. How does that benefit the popular appraisal of our field?

 Journalists and bloggers are free to discuss research they learn about at conferences, of course. And they typically do a good job in noting when findings are tentative (or giving enough details that others can evaluate the claims). But a formal press release from an academic society about unpublished research that is not available seems to me to be a different beast.

 Are there cases in which an academic society should issue a press release based on a conference presentation? Do you think this sort of press release is acceptable? I'd be curious to hear the perspectives of other scientists and science writers. Let me know what you think?

Tuesday, July 9, 2013

Pop Quiz - What can we learn from an intervention study?

Pop Quiz

1. Why is a double-blind, placebo-controlled study with random assignment to conditions the gold standard for testing the effectiveness of a treatment?

2. If participants are not blind to their condition and know the nature of their treatment, what problems does that lack of control introduce?

3. Would you use a drug if the only study showing that it was effective used a design in which those people who were given the drug knew that they were taking the treatment and those who were not given the drug knew they were not receiving the treatment? If not, why not?

Stop reading now, and think about your answers. 


Most people who have taken a research methods class (or introductory psychology) will be able to answer all three. The gold standard controls for participant and experimenter expectations and helps to control for unwanted variation between the people in each group. If participants know their treatment, then their beliefs and expectations might affect the outcome. I would hope that you wouldn't trust a drug tested without a double-blind design. Without such a design, any improvement by the treatment group need not have resulted from the drug.

In a paper out today in Perspectives on Psychological Science, my colleagues (Walter Boot, Cary Stothart, and Cassie Stutts) and I note that psychology interventions typically cannot blind participants to the nature of the intervention—you know what's in your "pill." If you spend 30 hours playing an action video game, you know which game you're playing. If you are receiving treatment for depression, you know what is involved in your treatment. Such studies almost never confront the issues introduced by the lack of blinding to conditions, and most make claims about the effectiveness of their interventions when the design does not permit that sort of inference. Here is the problem:
If participants know the treatment they are receiving, they may form expectations about how that treatment will affect their performance on the outcome measures. And, participants in the control condition might form different expectations. If so, any difference between the two groups might result from the consequences of those expectations (e.g., arousal, motivation, demand characteristics, etc.) rather than from the treatment itself.
A truly double blind design addresses that problem—if people don't know whether they are receiving the treatment or the placebo, their expectations won't differ. Without a double blind design, researchers have an obligation to use other means to control for differential expectations. If they don't, then a bigger improvement in the treatment group tells you nothing conclusive about the effectiveness of the treatment. Any improvement could be due to the treatment, to different expectations, or to some combination of the two. No causal claims about the effectiveness of the treatment are justified.

If we wouldn't trust the effectiveness of a new drug when the only study testing it lacked a control for placebo effects, why should we believe a psychology intervention if it lacked any controls for differential expectations? Yet, almost all published psychology interventions attribute causal potency to interventions that lack such controls. Authors seem to ignore this known problem, reviewers don't block publication of such papers, and editors don't reject them.

Most psychology interventions have deeper problems than just a lack of controls for differential expectations. Many do not include a control group that is matched to the treatment group on everything other than the hypothesized critical ingredient of the treatment. Without such matching, any difference between the tasks could contribute to the difference performance. Some psychology interventions use completely different control tasks (e.g., crosswords puzzles as a control for working memory training, educational DVDs a control for auditory memory training, etc). Even worse, some do not even use an active control group, instead comparing performance to a "no-contact" control group that just takes a pre-test and a post-test. Worst of all, some studies use a wait-list control group that doesn't even complete the outcome measures before and after the intervention.

In my view, a psychology intervention that uses a waitlist or no-contact control should not be published. Period. Reviewers and editors should reject it without further consideration -- it tells us almost nothing about whether the treatment had any effect, and is just a pilot study (and a weak one at that). 

Studies with active control groups that are not matched to the treatment intervention should be viewed as suspect—we have no idea what differences between the treatment and control condition were necessary. Even closely matched control groups do not permit causal claims if the study did nothing to check for differential expectations.

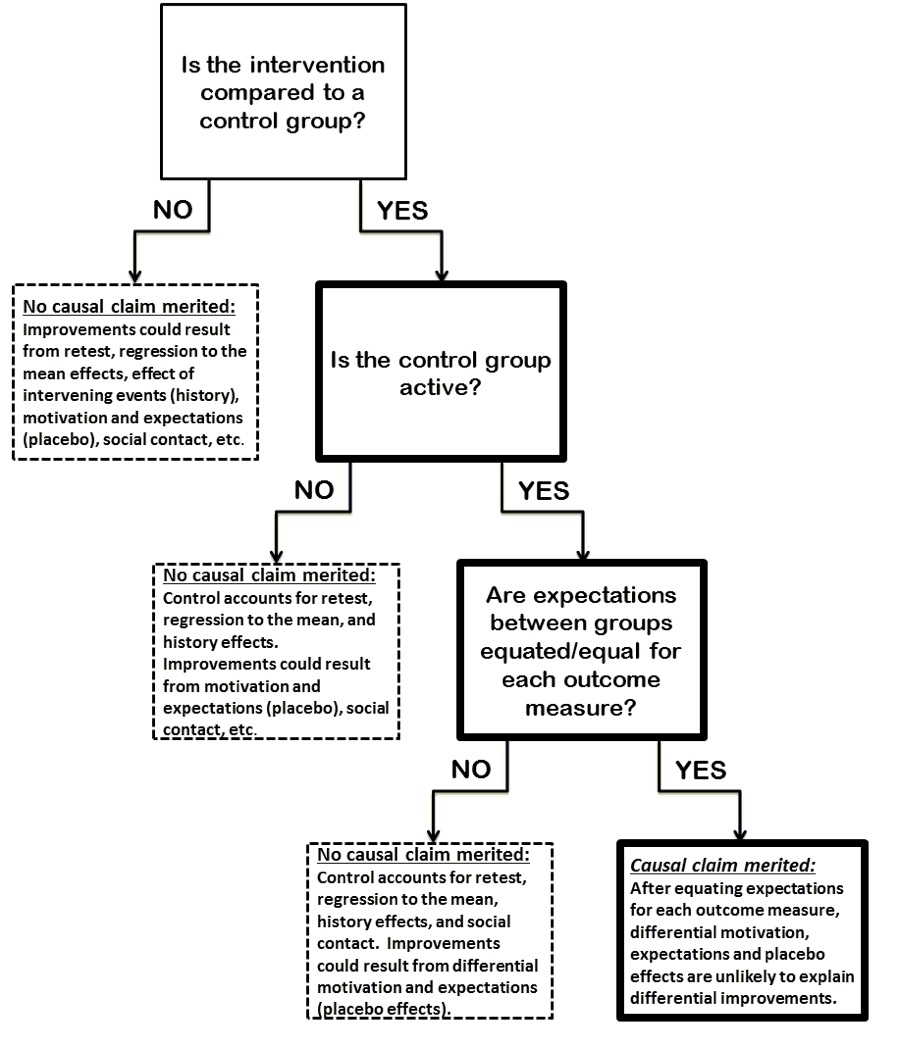
To make it easy to understand these shortcomings, here is a flow chart from our paper that illustrates when causal conclusions are merited and what we can learn from studies with weaker control conditions (short answer -- not much):

Figure illustrating the appropriate conclusions as a function of the intervention design


Almost no psychology interventions even fall into that lower-right box, but almost all of them make causal claims anyway. That needs to stop.


If you want to read more, check out our OpenScienceFramework Page for this paper/project. It includes an answers to a set of Frequent Questions.

Tuesday, July 2, 2013

Six simple steps scientists can take to avoid having their work misrepresented

Writing a journal article? Here are six simple steps you can take to avoid having your claims misinterpreted and misrepresented. None of these steps require any special analyses or changes to your lab practices. They are steps you should take when writing about your findings. I haven't always followed these steps in my own articles, but I will be in the future (whenever I have final say on a paper or can convince my collaborators).

  1. Do not speculate in your abstract. Abstracts are the place to report what you did, why you did it, and what you found. It is fine to report any conclusion that follows directly from your data. But, you should not use the abstract as a place to make claims that exceed your evidence. For example, even if you think your findings with undergrads in your laboratory might be relevant for a better understanding of autism, your abstract should not mention autism unless you actually studied it. Readers of your abstract (often the only thing people read) will assume that what you said is what you found, and media reports will focus on that your speculation rather than your findings.
  2. Separate planned and exploratory analyses and label them. If you registered your analysis plan and stick to it, you can mark those analyses as planned, documenting that you are testing what you originally intended to test. It is fine to explore your data fully, but you should flag any unplanned analyses as exploratory and note explicitly that they require replication and verification. Your exploratory analyses should be treated as speculative rather than definitive tests.
  3. Combine results and discussion sections. Justify each analysis and explain what it shows in the same place in your manuscript. If you separate your analyses and explanations, non-expert readers will skip your evidence and focus on your conclusions. By combining them, you allow the reader to better evaluate the link between your evidence and your conclusions.
  4. Add a caveats and limitations section. In your general discussion, you should add a description of any limitations of your study. That includes shortcomings of the method, but also limitations to the generalizability of your sample, effects in need of replication, etc. If your effects are small, you should note if and how that limits their practical implications. By identifying limitations and caveats in your paper, your readers will better understanding what your findings do and do not show.
  5. Specify the limits of generalization. Few papers do this, but all of them should. Most papers in psychology test undergraduates and then make claims as if they apply to all of humanity. Perhaps they do, but any generalization beyond the tested population should be justified. If you tested undergraduates and expect your studies to generalize to similar undergraduate populations, you should say so. If you think they also will generalize to the elderly or to children, you should say so and explain why. Spell out the characteristics of your sample that you think are essential to obtain your effect. Specifying generalization has benefits. First, it lets readers know the scope of your effects and helps them to predict whether they could obtain the same result with their own available population. Second, it clarifies the importance of your findings. If you expect that your effects are limited to subjects at your university in December of 2012 and won't generalize to other times or places, then it is less clear that anyone should care. Third, by specifying your generalization, you are making a more precise claim about your effect that others can then test. If you claim your effect should generalize to all undergraduates, then anyone testing undergraduates should be able to find it (assuming adequate statistical power), and if they can't, that undermines your claim. If you restrict generalization too much to protect yourself against challenges, then others will have no reason to bother testing your effect. Perhaps most importantly, if you appropriately limit your generalization in the paper itself, then media coverage will be less likely generalize your claims beyond what you actually intended.
  6. Flag speculation as speculation. If you must discuss implications that go beyond what your data show, explicitly flag those conclusions as speculative and note that they are not supported by your study. By calling speculation what it is, you avoid having others assume that your wildest and most provocative ideas are evidence-based. Speculation is okay as long as everyone reading your paper knows what it is.

Bonus suggestion: If you have a multiple-author paper, the Acknowledgements or Author's Note should specify each author's contributions clearly and completely. By doing so, you assign both credit and blame where it is deserved. For example, when I collaborate on a neuroimaging project, I make clear that I had nothing to do with any of the imaging data collection, coding, or analysis. I should get no credit for that part of a study (given that I know nothing about imaging), but I also should take no blame for any missteps in that part of the project.

Thursday, June 6, 2013

When beliefs and actions are misaligned - the case of distracted driving


Originally posted to the invisiblegorilla blog on 22 December 2010. I am gradually reposting all of my earlier blog posts from other sites onto my personal website where I will be blogging for the foreseeable future. The post is unedited from the 2010 version.

During the summer of 2010, the California Office of Traffic Safety conducted a survey of 1671 drivers at gas stations throughout California. The survey asked drivers about their own driving behavior and perceptions of driving risks. Earlier this year I posted about the apparent contradiction between what we know and what we do—people continue to talk and text while driving despite awareness of the dangers. The California survey results (pdf) reinforce that conclusion.
59.5% of respondents listed talking on a phone (hand held or hands free) as the most serious distraction for drivers. In fact, 45.8% of respondents admitted to making a mistake while driving and talking on a phone, and 54.6 claimed to have been hit or almost hit by someone talking on a phone. People are increasingly aware of the dangers. As David Strayer has shown, talking on a phone while driving is roughly comparable to driving under the influence of alcohol (pdf). Yet, people continue to talk on the phone while driving.
Unlike some earlier surveys that only asked general questions about phone use, this one asked how often the respondents talked on a phone in the past 30 days. 14.0% report regularly talking on a hand-held phone (now illegal) and another 29.4% report regularly talking on a hands-free phone. Fewer than 50% report never talking on a hands free phone while driving (and only 52.8% report never talking on hand-held phones). People know that they are doing something dangerous, but they do it anyway (at least sometimes).
Fewer people report texting while driving than talking while driving: 9.4% do so regularly, 10.4% do so sometimes, and another 10.6% do so rarely. In other words, more than 30% of subjects still text while driving, at least on occasion, even though texting is much more distracting than talking and is substantially worse than driving under the influence.
68% of respondents thought that a hands-free conversation is safer than a hand-held one, a mistaken but unfortunately common belief. The misconception is understandable given that almost all laws regulating cell phones while driving focus on hand-held phones. The research consistently shows little if any benefit from using a hands-free phone—the distraction is in your head, not your hands.
Fortunately, there is hope that education (and perhaps regulation) can help. The extensive education campaigns about mandatory seatbelt use and the dangers of drunk driving have had an effect over the years: 95.8% report always using a seat belt, and only 1% report never wearing a seatbelt. Only 5.9% reported having driven when they thought they had already had too much alcohol to drive safely.
Sources cited:
Strayer, D., Drews, F., & Crouch, D. (2006). A Comparison of the Cell Phone Driver and the Drunk Driver Human Factors: The Journal of the Human Factors and Ergonomics Society, 48 (2), 381-391 DOI: 10.1518/001872006777724471

Wednesday, June 5, 2013

Continuing the "diablog" with Rolf Zwaan -- still more thoughts

+Rolf Zwaan just continued our "diablog" (love that term) on reliability and replication. (Rolf -- sorry for slightly misrepresenting your conclusion in my last post, and thanks for clarifying.) At this point, I think we're in complete agreement on pretty much everything in our discussion. I thought I'd comment on one suggestion in his post that was first raised by +Etienne LeBel in the comments on Rolf's first post and that Rolf discussed in his most recent post.

The idea of permitting additional between subjects conditions on registered replication reports is an interesting one. As Rolf notes, that won't work for within-subject designs as the new conditions would potentially affect the measurement of the original conditions. I have several concerns about permitting additional conditions for registered replication reports at Perspectives, but I don't think any of them necessarily precludes additional conditions. It's something the other editors and I will need to discuss more. Here are the primary issues as I see them:  


  • The inclusion of additional conditions should not diminish the sample size for the primary conditions. Otherwise, it would lead to a noisier effect size estimate for the crucial conditions, undermining the primary purpose of the replication reports. Given subject pool constraints and our desire to measure the crucial effects with a maximimal sample size, that could be a problem, particularly at smaller schools.
  • The additional condition must in no way affect the measurements in the primary condition. That is, subjects in the primary conditions could not be aware of the existence of an additional condition. Some measures would need to be taken to avoid any interactions among subjects. That's already something we account for in most designs, so I don't see this as a major impediment.
  • The additional conditions could not be reported alongside the primary analyses in the printed journal article. The issue here is that we want the final published article to report the same measures and tests for each individual replication attempt. Otherwise, the final report will become unwieldy, with each of the many participating labs reporting different analyses. That would hinder the ability of readers to assess the strength of the primary effect under study.
If we do decide to permit additional between-subjects conditions, analyses of those conditions could be reported on the OSF project pages created for each participating lab. There are no page limits for those project pages, and each lab could discuss their additional conditions more fully. I will make sure the other editors (+Alex Holcombe and +Bobbie Spellman) and I discuss this possibility.


The Value of Pre-Registration - comments on a letter in the Guardian

The Guardian just published a great letter, signed by many of the leaders of our field, calling for pre-registration as a way to improve our science. I imagine they would have had many more signatories if the authors had put out a more public call. I'll add my virtual signature here. If you agree with the letter, please make sure your colleagues see it and add your virtual signature as well.

I think pre-registration is the way forward. I hadn't pre-registered my studies before this past year, but I've started doing that for all of the studies for which I have direct input into the management of the study. I hope more journals will begin to conduct the review process before the data are in, vetting the method and analysis plan and then publishing the results regardless of the outcome. But even if they don't, pre-registration is the one way to demonstrate that the planned analyses weren't p-hacked. My bet is that, as the ratio of pre-registered to not-pre-registered studies in our journals grows, researchers will begin to look askance at studies that were not pre-registered. The incentive to pre-register will increase as a result, and that's a good thing.


Even if journals don't accept studies before data collection, pre-registration helps to certify that the research showed what it claimed to show. And, pre-registration does not preclude exploratory analyses. They can just be flagged as such in the final article, and readers will know to treat this explorations as preliminary and speculative, requiring further verification. I personally favor having two labeled headings in every results section, one for planned analyses and one for exploratory analyses. Even without pre-registration, that's a good approach. But pre-registration certifies the planned ones.

It's easy to pre-register your results and post your data publicly. You can do that with a free account at OpenScienceFramework.org.


update: fixed formatting errors.